Sprint planning for the next two weeks
Planning starts with manual research instead of decisions. Blockers surface late and half-ready stories enter the sprint.
The work already crosses these systems:
From scattered checks to one governed run.
Today
The scrum master checks Jira backlog and velocity, reads Confluence for open design questions, and cross-checks Monday.com for dependencies before the meeting even starts.
With NopsAI
A scheduled pipeline pulls backlog, velocity, spec-readiness and dependency data, uses a fast LLM profile to summarize story readiness, and drops a planning brief automatically.
Planning starts with prepared evidence instead of tool-hopping.
The run, step by step.
Deterministic work first, reasoning inside the tools and written policies the pipeline bound to it, and a named human at every gate its author placed.
Trigger
A schedule fires the morning before planning, using a service account scoped to the delivery team.
Collect context
Backlog, velocity history, spec pages and cross-team dependencies are read through approved tools.
Verify state
Deterministic checks flag stories missing estimates, acceptance criteria or an owner.
Reason
A fast LLM profile summarizes readiness per story and highlights the dependencies that will bite.
Approve
No gate needed — the run produces a document, not a change.
Execute and record
The planning brief is published as a run-owned Markdown output the team can cite in the meeting.
What the run leaves behind.
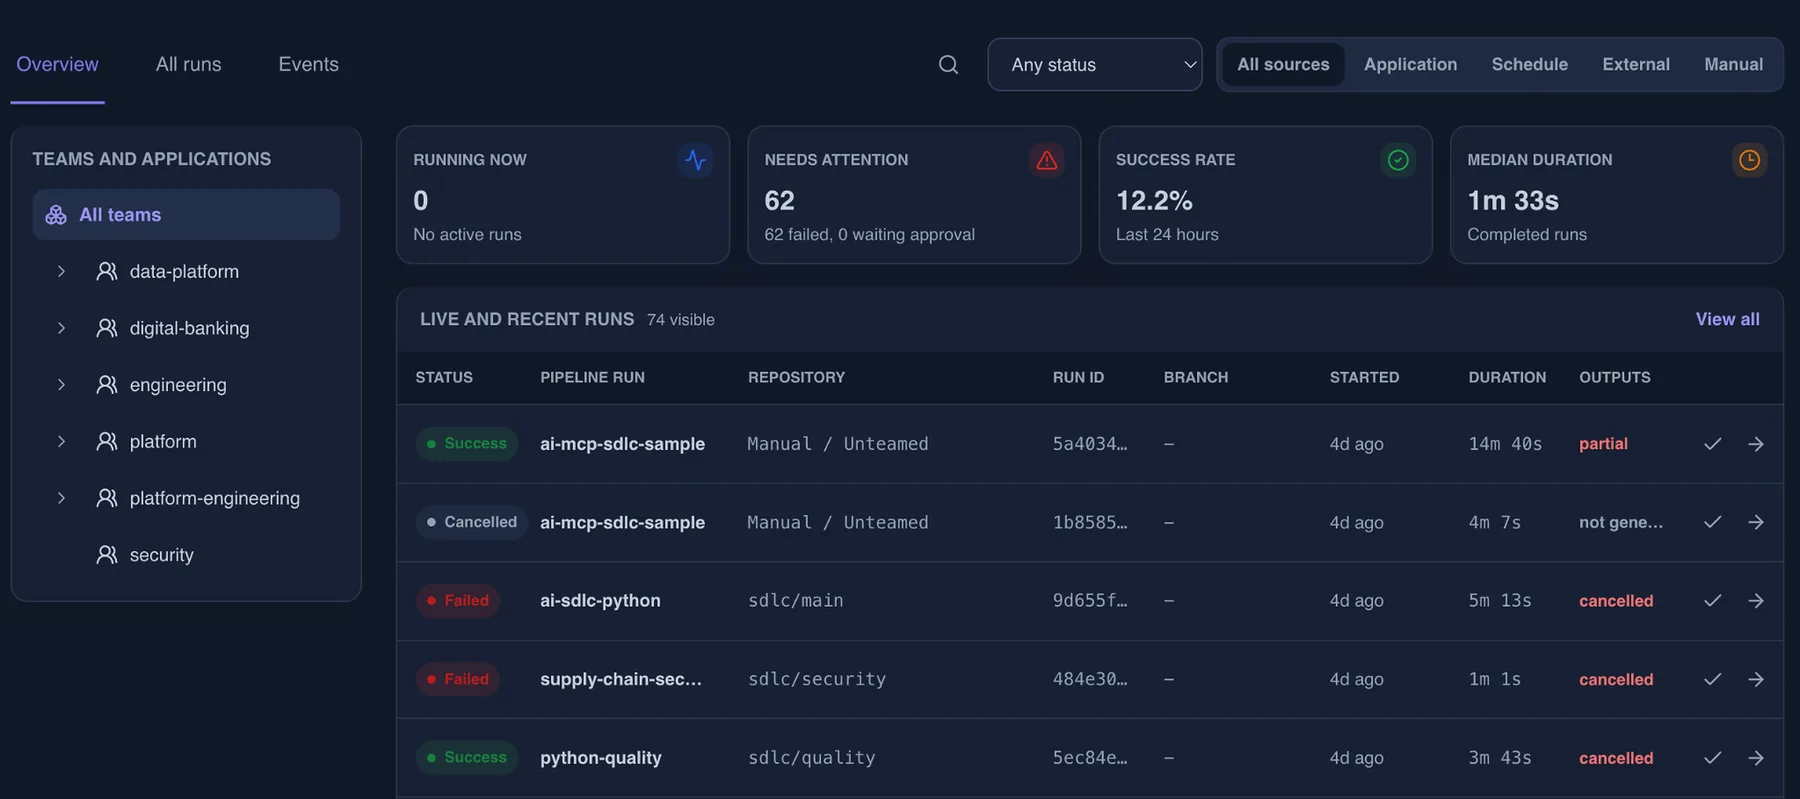
The useful part is not only the automation. It is repeatability with proof.
Trigger and subject
What started the run and which effective identity it ran as.
Authorization snapshot
Which resources were checked, and which decision each check returned.
Knowledge in scope
The guardrails, policies and runbooks that bounded each decision, stored as text with the run, plus the governance level that applied.
Tool and AI activity
Every tool call, the profile that allowed it, and the model usage it consumed.
Task history and timings
Every task, its state transitions, its duration and the logs it produced, with known secret values masked.
Approvals and outputs
Who approved, when, and the deliverables the run produced.
← A customer-reported bug needs to ship as a hotfix
The fix is small, but no single durable trail connects the complaint, the code change, the test result and the emergency approval.
Production incident at 2 a.m. →
At 2 a.m. the hard part is finding what changed and deciding whether rollback is safe — fast, without losing the evidence trail.
Map this workflow against your controls.
Bring the trigger, the tools it touches, the approvers, the runtime boundary and the evidence you need to keep.