A CI/CD pipeline suddenly starts failing
Most failures are a diagnosis problem before they are an engineering problem, and diagnosis eats the first thirty minutes.
The work already crosses these systems:
From scattered checks to one governed run.
Today
An engineer reruns the job, compares it to the last green build by eye, checks whether a runner went offline, then starts bisecting commits.
With NopsAI
The pipeline diffs the failing run against last-known-good, checks runner health, requeues on disconnect, and an AI goal step summarizes the likely cause from commits, logs and config.
The first thirty minutes of guessing becomes a governed diagnosis workflow.
The run, step by step.
Deterministic work first, reasoning inside the tools and written policies the pipeline bound to it, and a named human at every gate its author placed.
Trigger
A failed build webhook, or a monitoring alert on repeated failures in the same pipeline.
Collect context
The failing run, the last successful run, changed files and runner health are pulled together.
Verify state
Deterministic checks separate infrastructure failures from genuine test or build regressions.
Reason
An AI goal ranks likely causes from the diff, the logs and the configuration change history.
Approve
Only required if the proposed action is a config change or a runner pool adjustment.
Execute and record
A requeue or fix proposal is recorded with the diagnosis, so the next occurrence starts ahead.
What the run leaves behind.
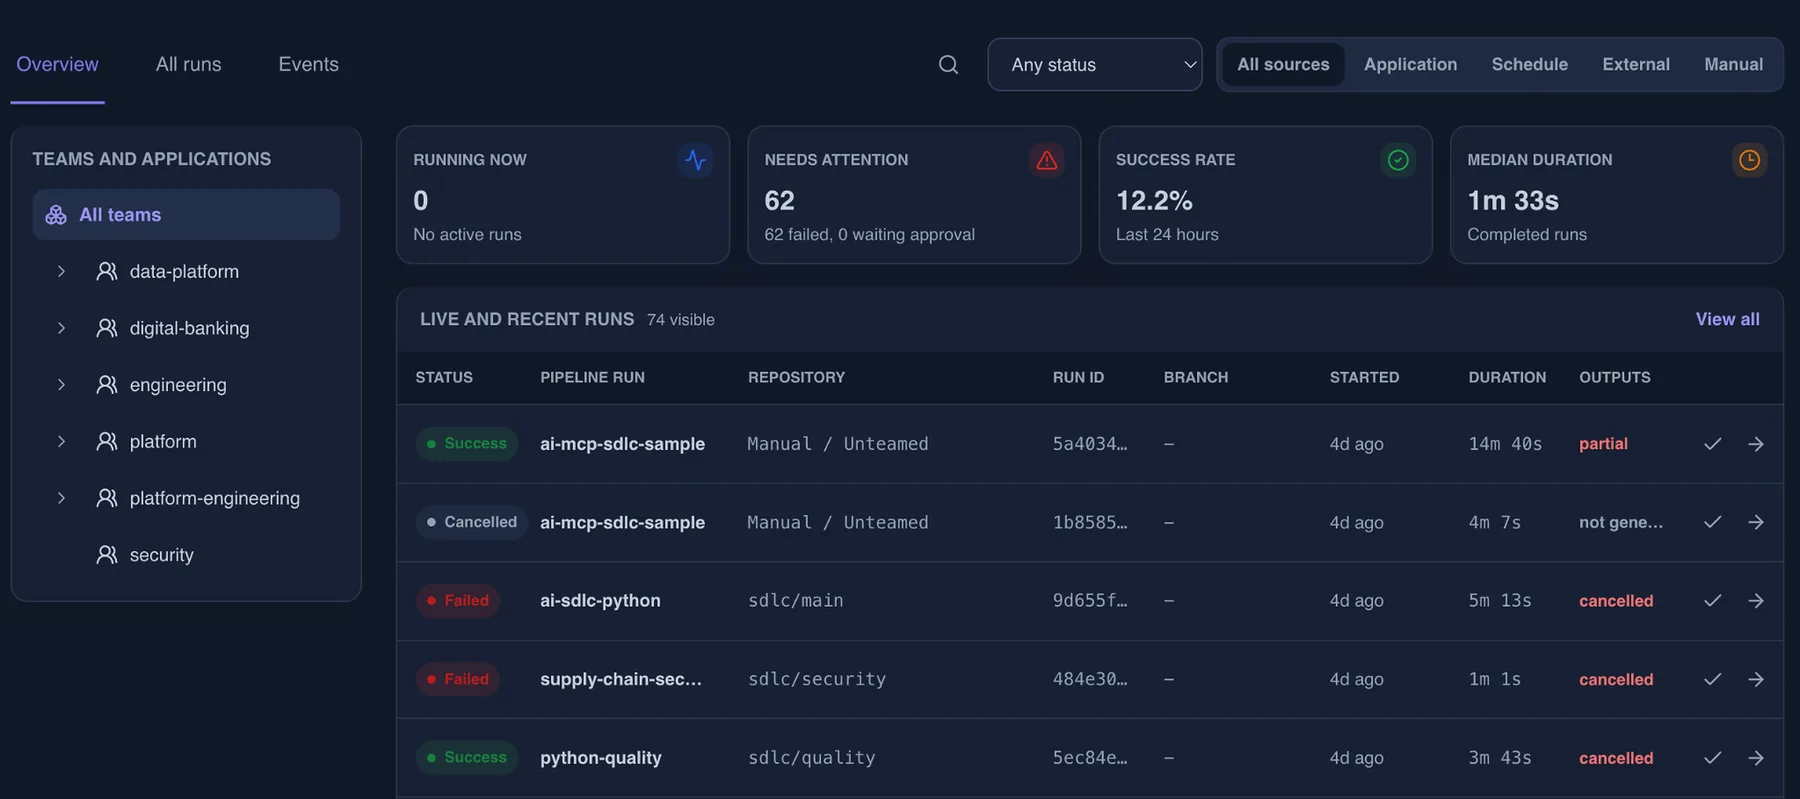
The useful part is not only the automation. It is repeatability with proof.
Trigger and subject
What started the run and which effective identity it ran as.
Authorization snapshot
Which resources were checked, and which decision each check returned.
Knowledge in scope
The guardrails, policies and runbooks that bounded each decision, stored as text with the run, plus the governance level that applied.
Tool and AI activity
Every tool call, the profile that allowed it, and the model usage it consumed.
Task history and timings
Every task, its state transitions, its duration and the logs it produced, with known secret values masked.
Approvals and outputs
Who approved, when, and the deliverables the run produced.
← Preparing a release
Scope mismatch, unmerged PRs, failed gates and an outdated runbook can all cause a late surprise.
Sales promises a feature that does not exist yet →
Sales needs a fast answer; product needs control. Without a governed path, promises get made on incomplete information.
Map this workflow against your controls.
Bring the trigger, the tools it touches, the approvers, the runtime boundary and the evidence you need to keep.